
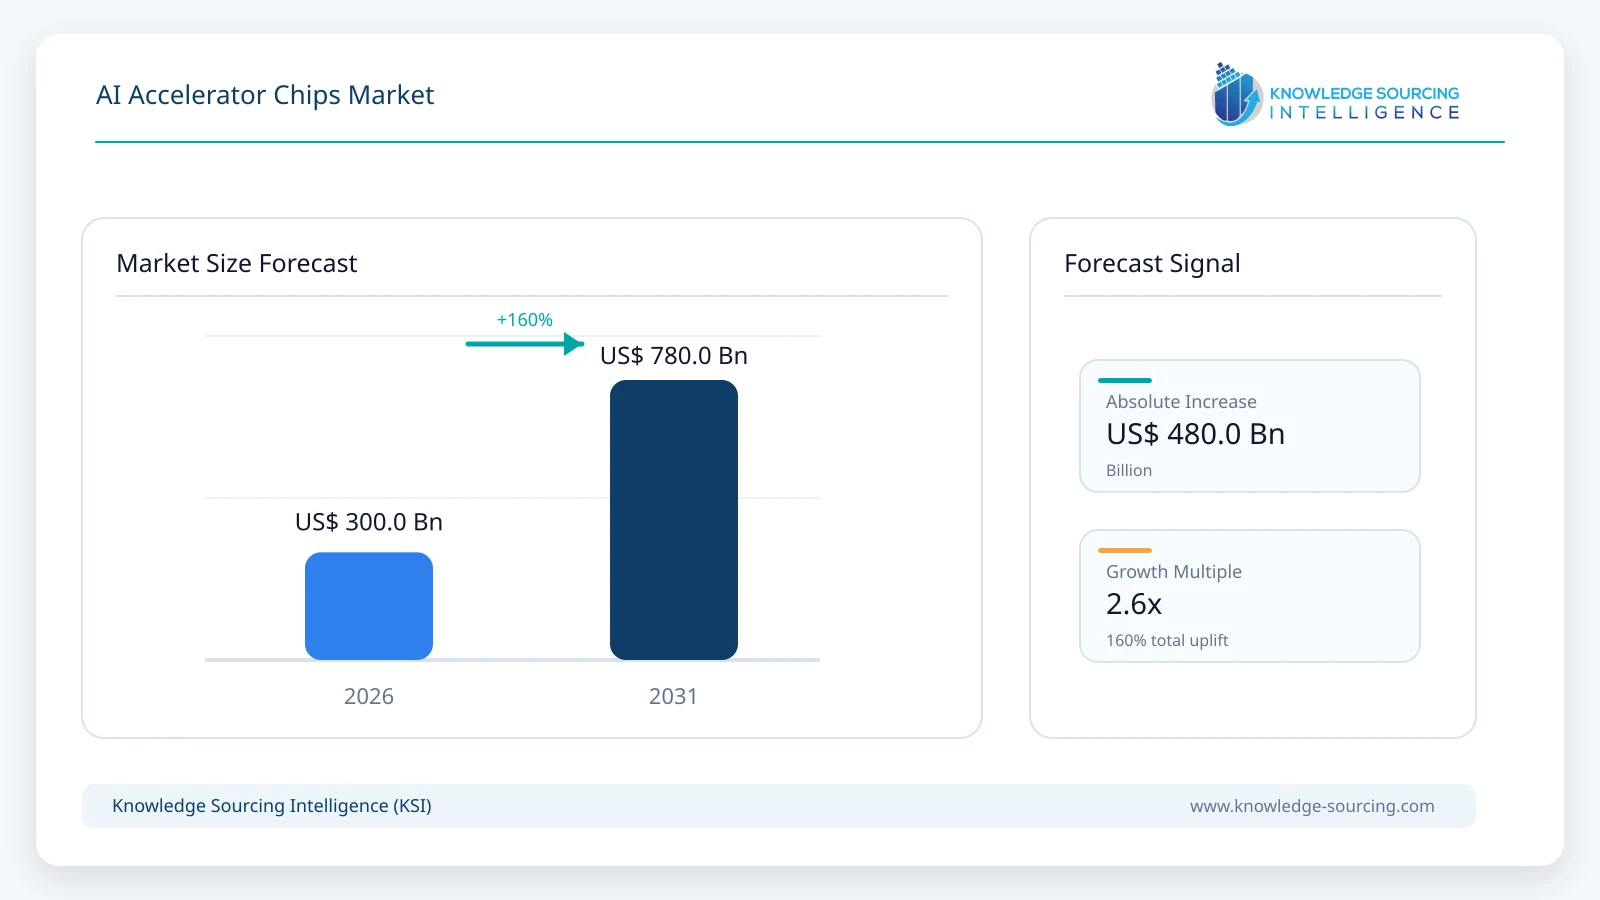
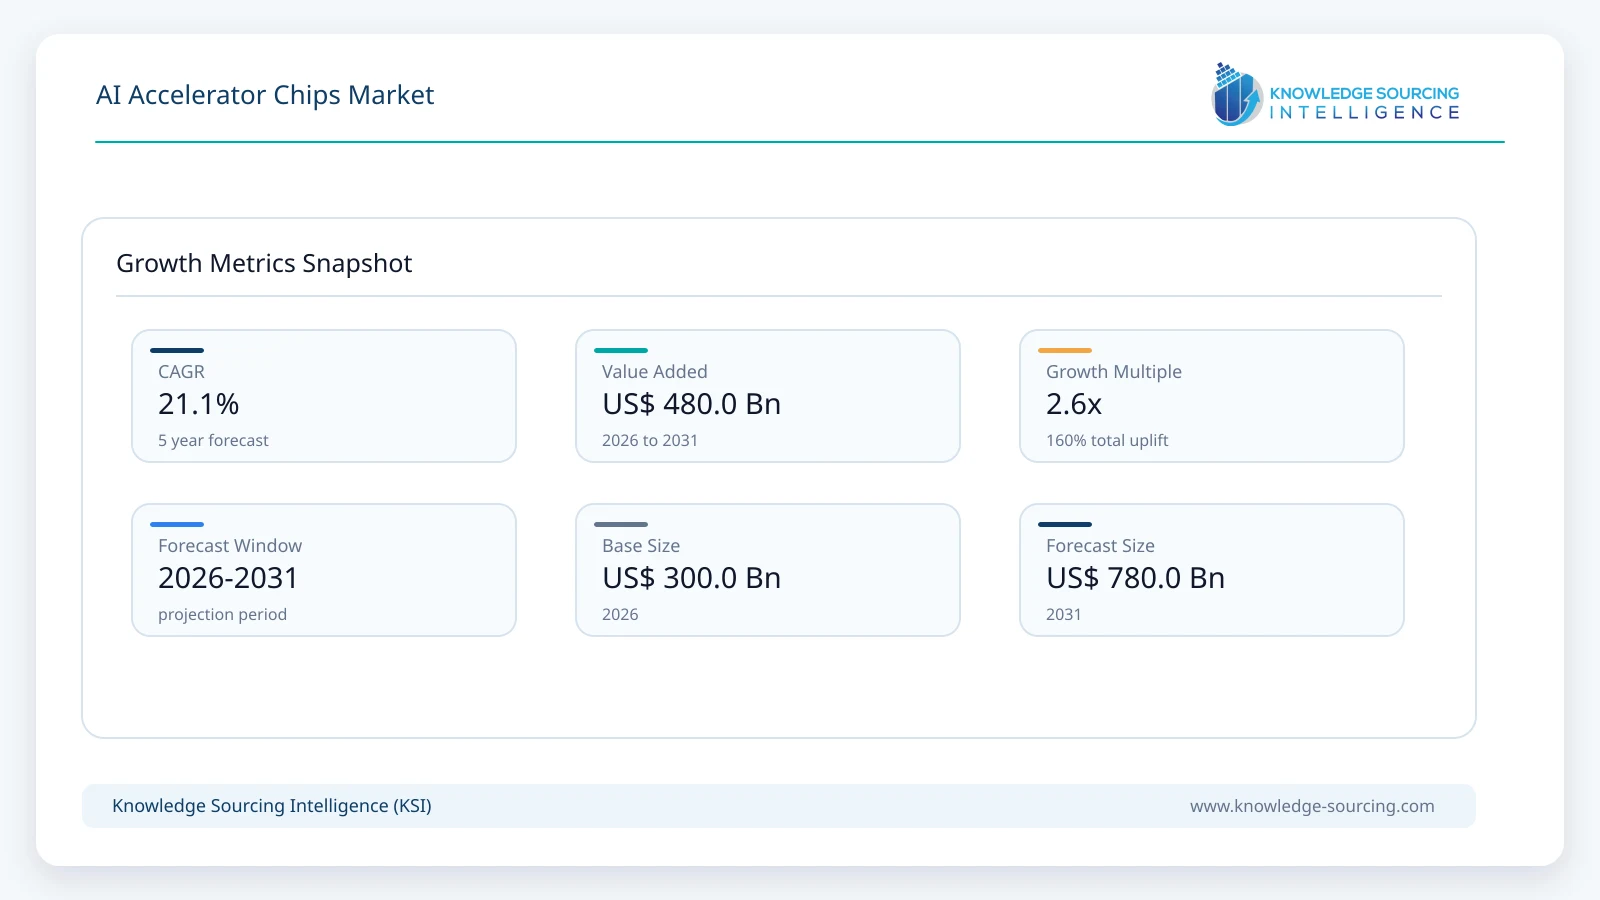
The AI Accelerator Chips Market is expected to expand at an estimated CAGR of 21.1%, reaching approximately USD 780 billion in 2031 from USD 300 billion in 2026.
Highlights:
- 1GPU designs account for an estimated 78% of accelerator-chip value in 2026, reflecting merchant demand for programmable training and flexible inference hardware.
- 2Cloud-based deployment remains the principal purchasing channel; edge processors compete through power and integration requirements rather than the same cluster-scale specifications.
- 3Dedicated inference ASICs and hyperscaler silicon are gaining ground in repeatable workloads for which design costs can be spread across substantial installed fleets.
- 4HBM delivery, wafer capacity and advanced packaging reservations increasingly influence contractual access to leading processors.
- 5Automotive, manufacturing and medical applications depend on longer qualification cycles than cloud infrastructure and require continuity of software and silicon supply.
- 6North American hyperscalers shape the largest procurement programs, while Asia Pacific is expected to gain a larger share of deployed accelerator demand through 2031.
AI accelerator chips execute matrix operations, neural-network inference and related workloads on specialized processing architectures. The market spans data-center GPUs, application-specific accelerators, tensor processors, embedded NPUs and FPGA configurations sold or deployed for identifiable AI purposes. Purchases are assessed at attributable semiconductor value rather than the invoice for an entire server rack. Conventional server CPUs, separately sold memory, cloud inference subscriptions and data-center construction do not form part of the processor market merely because they support AI services.
Merchant accelerator suppliers typically ship products to multiple customers, whereas cloud operators may commission proprietary designs for controlled internal deployment. Google offers TPU capacity within its cloud operations and to selected partners; Microsoft has introduced its Maia processor family for Azure workloads. These arrangements carry different economic terms from a discrete GPU sale. In each case, the buyer ultimately compares usable inference performance, memory capacity, software migration expense and the availability of complete systems at the intended installation date.
Market Overview
NVIDIA recorded USD 89.0 billion of Data Center revenue during its quarter ended July 2026. This includes a broader platform than accelerator chips alone, but it provides a clear indication of the scale of systems now being ordered. AMD reported USD 6.7 billion of Data Center sales in the second quarter, a business that also includes EPYC CPUs and other devices. Broadcom reported USD 16.7 billion of quarterly AI semiconductor revenue, encompassing custom accelerators and networking.
Google announced separate TPU 8t and 8i architectures in April 2026, targeting model training and latency-sensitive inference. Microsoft subsequently confirmed that Maia 200 was serving production workloads, while Meta continues to deploy its MTIA family for recommendation and generative workloads. Internally designed processors do not remove demand for merchant hardware: large cloud operators still need flexible systems for new models, research and customer-specific deployments.
Market Trends
Inference Workloads Are Changing Custom-Silicon Economics
Microsoft confirmed on 12 October 2026 that Maia 200 was operating in production and set out a broader deployment plan for 2027. A processor designed for predictable model-serving traffic can trade some programming flexibility for greater efficiency on the specific task. The benefit is substantial only when the operator can keep the hardware utilized and maintain its own compiler and runtime environment over several generations.
Broadcom participates in this transition through custom processors supplied to large customers, while Google and Meta invest in internally controlled designs. Merchant GPUs retain value when workload definitions change or research teams need a widely supported development stack. The market is consequently dividing by the ability of the buyer to finance software maintenance and amortize design work, not simply by whether a processor can execute a neural network.
Chip Performance Is Increasingly Set by Memory and System Interconnect
Larger reasoning models place considerable pressure on the movement of data between memory and compute. Google’s TPU 8t and 8i announcement distinguishes training needs from low-latency serving, and Qualcomm’s June 2026 Dragonfly roadmap similarly emphasized memory-adjacent processing for inference.
System designers therefore select HBM configurations, on-package SRAM, interconnects and software together. A stronger memory subsystem can raise usable tokens per watt without requiring every processing unit to run at its nominal limit. Vendors able to coordinate chip architecture with the available memory and packaging supply are more likely to meet contracted deployment dates.
Advanced Packaging Capacity Is Becoming a Procurement Commitment
On 21 October 2026, NVIDIA announced capacity agreements across substrates, advanced packaging and testing. Its plans with Amkor and other partners reflect the manufacturing effort required before next-generation devices can enter volume data-center builds. Leading GPUs and custom ASICs rely on tightly controlled integration of processing dies, HBM and interposers; expanding wafer output without corresponding packaging capacity would not supply more complete accelerators.
Customers are increasingly exposed to the timing of multiple suppliers rather than a single semiconductor fab. Qualification of a new package or substrate source takes time, and yield losses can change effective availability even when nominal installed capacity rises. Long-term supply contracts may consequently matter as much as the upfront processor specification.
AI Processing Is Becoming an Embedded Design Requirement
NPUs incorporated into smartphones and client devices are optimized for local inference where continuous network access is expensive or undesirable. Industrial controllers and automotive computing platforms add different constraints, including predictable latency, functional safety and a long service life.
Edge silicon is less expensive per device than high-end data-center hardware, but device volumes and rising model complexity support an expanding pool of attributable semiconductor value. Software portability remains decisive: manufacturers cannot replace a processor easily once the application has been qualified around a particular compiler, driver stack or power-management architecture.
Segment Analysis
By Chip Type: GPU
Data-center GPUs retain the broadest portfolio of supported training and inference applications. The combination of high memory bandwidth, mature programming tools and established distributed-computing libraries reduces development risk for customers supporting several model families. NVIDIA’s commercial deployments and AMD’s Instinct line illustrate the value placed on programmable computing that can be repurposed as models evolve.
Under the modeled chip-type mix, GPU-attributable value reaches approximately USD 491.4 billion in 2031, while custom ASICs, TPUs and NPUs take a larger collective share. Customers buying GPUs may accept a higher acquisition price in exchange for flexibility and lower software migration costs.
By Processing Type: Cloud
Cloud deployments represent an estimated 91% of 2026 accelerator value, reflecting large processor counts and high unit content in model training and hosted inference. Cloud operators buy complete computing environments, but chip economics can be evaluated separately from racks, networking and construction.
By 2031, cloud processing is projected to account for about USD 678.6 billion in chip value. Its share moderates as NPUs become more common in personal electronics, vehicles and industrial products, yet absolute cloud demand continues to expand.
By Application: Generative AI
Generative model training, reasoning and token-serving workloads are expected to account for approximately USD 147.0 billion of accelerator-chip value in 2026. Procurement is concentrated where operators can run substantial models repeatedly and sell inference capacity or AI-enabled services to other businesses.
The segment is modeled to grow faster than the total market as commercial use shifts from experimentation into sustained inference. In 2031, its modeled share reaches 53%, reflecting more processors assigned primarily to generative workloads rather than stand-alone NLP or conventional high-performance computing.
By Industry: IT and Telecommunications
Cloud service providers, AI infrastructure operators and telecommunications groups purchase accelerator chips to support externally delivered computing, hosted models and enterprise services. Their role differs from the sector ultimately using an AI application: a hospital buying cloud inference does not necessarily purchase an accelerator, whereas the hosting provider does.
IT and telecommunications is forecast to represent 65% of the market by 2031, compared with a modeled 67% in 2026. Consumer devices, embedded industrial systems and dedicated vehicle processors gain some proportional weight, although hyperscalers still determine the largest individual orders.
Market Drivers
Hyperscale Deployment of Generative and Agentic AI
NVIDIA’s USD 89.0 billion Data Center quarter in 2026 and the expanding custom-chip programs at Microsoft and Google show how sustained model deployment is raising the amount of accelerated computing installed. Training requires dense parallel execution, while recurring inference generates a different utilization and memory profile. The two demands overlap but support different hardware purchasing decisions.
Cloud operators also have an incentive to keep multiple hardware options available. A proprietary inference processor can lower unit economics for familiar tasks, while merchant GPUs provide flexibility for emerging models. This dual-sourcing behavior broadens design activity without implying that every processor family will receive equivalent deployment volumes.
Demand for Higher Token Throughput per Watt
Energy and cooling limits impose practical ceilings on accelerator deployment even when buyers have the capital to order additional chips. A processor with lower inference cost can free electrical and facility capacity for more model requests, improving the economics of an operating data center.
The procurement effect is particularly strong for repetitive model-serving tasks where workload characteristics are understood. Custom ASICs and inference-specialized chips can compete where the saving in power and installed infrastructure exceeds the expense of software optimization and long-term support.
Growth of Locally Executed AI in Devices and Machines
Smartphones, industrial equipment and vehicles increasingly execute selected vision, speech and control functions on local processors. On-device inference reduces network dependence and may improve response times when decisions cannot wait for a cloud round trip. Qualcomm and other embedded semiconductor firms integrate NPUs within SoCs, while specialized industrial platforms package inference acceleration alongside conventional control functions.
The revenue effect depends on attributable AI processing content rather than the selling price of the complete device. Extensive qualifications for automotive or medical use slow replacement but can make a successful design persistent over several product years.
Commercialization of Proprietary Cloud Silicon
Google’s TPU portfolio and Microsoft’s Maia program demonstrate that leading cloud firms are willing to finance multiple generations of custom accelerators. The attraction is control over memory architecture, software execution and the hardware features most relevant to internally hosted services.
Such contracts can create sizable, multi-year semiconductor demand with fewer customers than the open merchant market. They also concentrate forecasting risk: a change in one hyperscaler’s model architecture or investment cadence can affect a supplier’s production schedule.
AI Computing Capacity Outside Established Technology Centers
More enterprises and governments are building local AI computing capacity for data control, language requirements or national infrastructure goals. Procurement increasingly includes accelerator clusters capable of supporting both generic models and local fine-tuning. These projects diversify the geographic destination of processors, although purchases may still be negotiated through major cloud platforms headquartered elsewhere.
Deployment will remain uneven because access to electricity, suitable facilities and skilled operators can constrain purchases. Suppliers with configurable systems and long-term support may reach these customers more effectively than vendors depending only on the highest-end training benchmark.
Market Restraints
Constraints in HBM, Packaging and Leading-Edge Capacity
The most demanding AI accelerators require tightly matched deliveries of logic dies, memory stacks, substrates and packaging services. NVIDIA’s October 2026 supply-chain expansion announcement points to a production system where additional chip demand cannot be satisfied by wafer starts alone.
Contracting for future capacity reduces some risk but can tie up working capital and complicate planning if model demand or architecture shifts. Smaller semiconductor companies may face less bargaining power when seeking access to the same fabrication and assembly partners used by established suppliers.
Software Portability and Framework Dependence
Accelerators are purchased with an expectation that established model software will run efficiently. CUDA libraries, compiler maturity, kernel optimization and distributed training tools can therefore outweigh theoretical performance advantages offered by competing designs. A move to proprietary hardware may require significant redevelopment of inference runtimes, debugging tools and model-serving systems.
Customers with large dedicated engineering teams can absorb these costs more readily than smaller enterprises. For a new chip provider, limited software adoption can restrict effective demand even after the silicon performs well in selected benchmarks. Sustained developer support is an operating expense that continues beyond the first hardware release.
Electricity, Rack Density and Site Commissioning
Modern accelerator infrastructure depends on high-capacity electrical connections, cooling plant, fiber links and equipment integration. A purchase agreement for processors does not ensure that the destination facility can energize and operate those processors on the announced timetable.
The constraint is particularly important for operators expanding into new geographical markets without an established AI data-center base. Processor suppliers have limited direct control over these facilities but bear the consequences of postponed deployments and changing customer inventory decisions.
Export Controls and Fragmented Regional Product Requirements
Rules governing advanced-computing exports affect which processors may be supplied to particular buyers or destinations. Designers may offer different specifications by geography, while customers reassess the longevity of software support and spare-parts access. These constraints can reduce economies of scale and increase qualification work, particularly for data-center chips built at the most advanced process nodes.
The commercial effect is not uniform across all accelerator categories. Lower-power edge NPUs and mid-range devices face different restrictions from the highest-performance cloud systems. Manufacturers need product-level compliance processes rather than broad assumptions that all AI chips share one export status.
Economic Risk in Concentrated Customer Programs
A substantial share of leading accelerator value is purchased by a limited group of cloud firms. Suppliers serving custom programs may invest heavily in non-recurring design engineering, production commitments and validation infrastructure before the customer begins volume deployment.
Merchant products spread risk across more buyers but also face inventory volatility and pricing competition. Captive designs introduce further uncertainty because their value may be embedded in cloud operations rather than recognized as third-party chip revenue. Commercial forecasts must therefore avoid treating announced power capacity or prospective rack counts as shipments already completed.
Regional Outlook
North America
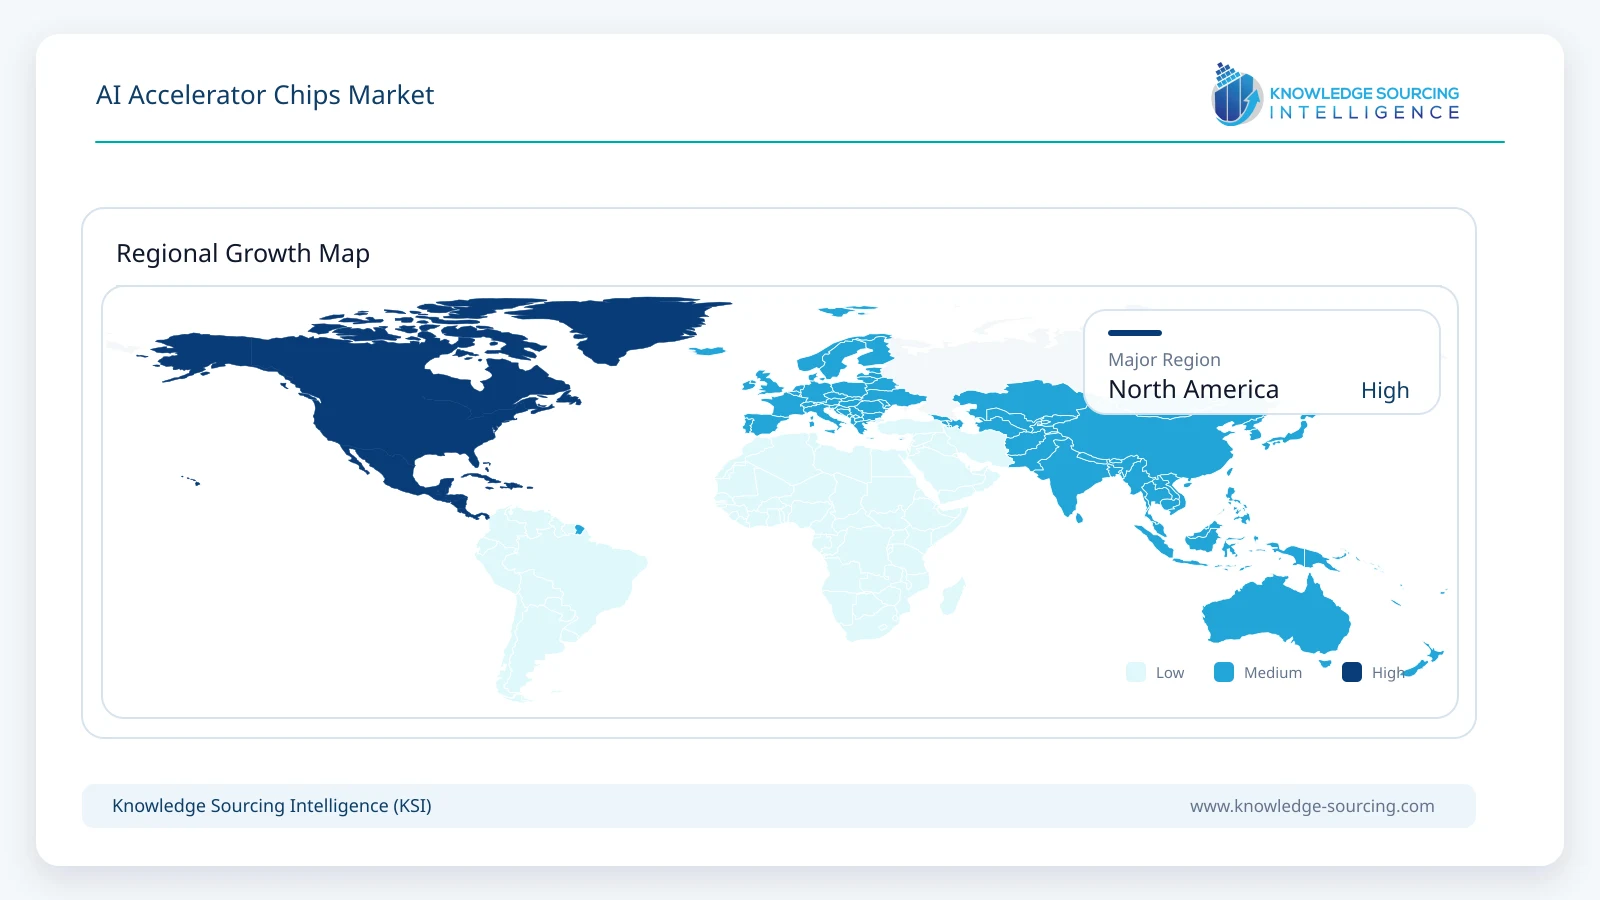
North America represents an estimated 46% of global chip value in 2026, driven by hyperscale procurement and domestic semiconductor design activity. NVIDIA, AMD, Broadcom, Microsoft, Google and Meta make major product and platform decisions in the United States, although their wafers and packages are often produced elsewhere.
Revenue is modeled to approach USD 327.6 billion by 2031, equivalent to roughly 42% of the global total and approximately 18.9% annual growth. Cloud demand remains the principal driver, supported by investment in AI services and computing capacity.
Asia Pacific
AI accelerator demand in Asia Pacific spans Chinese cloud infrastructure, Japanese and South Korean enterprise computing, Indian AI deployments and edge electronics manufacturing. Taiwan’s foundry and packaging ecosystem is strategically important to global supply, but production for a U.S. customer is not automatically local chip consumption.
Asia Pacific is estimated at USD 96.0 billion in 2026 and projected to reach USD 296.4 billion by 2031, implying growth of approximately 25.3% annually. Its modeled global share increases from 32% to 38%. Domestic chip-development programs, expanding regional AI services and growing embedded-device content support the outlook, although manufacturing bottlenecks and regulation create substantial differences between countries.
Competitive Landscape
The semiconductor industry contains several distinct competitor groups rather than a single interchangeable chip supplier set. NVIDIA and AMD provide programmable AI processors for multiple customers; Broadcom and Marvell participate in custom silicon programs; Qualcomm and MediaTek supply embedded processing; Google, Microsoft, Amazon and Meta develop proprietary accelerators for their own computing fleets.
NVIDIA’s software ecosystem, manufacturing allocations and installed systems support merchant-chip positioning. AMD offers an alternative programmable architecture through Instinct, while custom ASIC developers work with buyers willing to finance workload-specific design. Google’s TPUs and Microsoft’s Maia illustrate the integration advantage available to vertically involved cloud firms.
Recent Developments
21 October 2026: NVIDIA announced capacity initiatives with substrate, testing and advanced-packaging partners, including planned expansions at Amkor and KYEC. These agreements address manufacturing constraints for future accelerated-computing platforms; they are capacity plans, not completed output.
12 October 2026: Microsoft confirmed that its Maia 200 accelerator was serving production Azure workloads and outlined multi-gigawatt deployments beginning in 2027, showing a move from custom-silicon development to operating inference infrastructure.
2 September 2026: Broadcom disclosed USD 16.7 billion in fiscal third-quarter AI semiconductor revenue, including custom accelerators and networking, and guided to further expansion in the next quarter.
26 August 2026: NVIDIA reported USD 89.0 billion in quarterly Data Center revenue and said the Vera Rubin platform was moving through production deployment, reflecting sustained procurement of accelerated-computing systems.
24 June 2026: Qualcomm introduced the Dragonfly AI300 inference accelerator roadmap alongside memory-focused technologies and additional data-center products, extending its planned position beyond embedded AI devices.
22 April 2026: Google unveiled the eighth-generation TPU 8t and 8i designs for large-model training and latency-sensitive agentic inference, differentiating processors by workload rather than presenting one general-purpose configuration.
Market Outlook
The market through 2031 will be shaped by the balance between general-purpose acceleration and processors engineered for repeatable inference. Merchant GPUs should retain strong demand in heterogeneous computing environments, while proprietary ASIC and TPU programs can gain share where software teams control large volumes of stable workloads.
Cloud procurement will still account for most semiconductor value, but edge devices add a separate growth engine through integrated NPUs. Regional demand is expected to become less concentrated as Asia Pacific adds AI computing capacity, although North American buyers remain central to the industry’s largest contracts. Suppliers that deliver predictable application performance, portable development tools and credible multiyear manufacturing commitments should be better positioned than those whose advantages depend on a single headline benchmark.
AI Accelerator Chips Market Scope
| Report Metric | Details |
|---|---|
| Total Market Size in 2026 | USD 300 billion |
| Total Market Size in 2031 | USD 780 billion |
| Forecast Unit | Billion |
| Growth Rate | 21.1% |
| Study Period | 2021 to 2031 |
| Historical Data | 2021 to 2024 |
| Base Year | 2025 |
| Forecast Period | 2026 – 2031 |
| Segmentation | Chip Type, Processing Type, Application, Industry, Geography |
| Companies |
|
| Customization Scope | 15% Free Customization included with purchase — Request Custom Breakdown → |
| Sample & Data Access | PDF Sample, Excel Databook & Analyst Briefing — Download Free Sample → |
Market Segmentation
By Chip Type
GPU
ASIC
FPGA
CPU
TPU
NPU
Others
By Processing Type
Edge
Cloud
By Application
Natural Language Processing
Computer Vision
Robotics
Autonomous Driving
Generative AI
High-Performance Computing
Others
By Industry
Automotive
Consumer Electronics
Healthcare
Manufacturing
BFSI
IT and Telecommunications
Retail and E-commerce
Aerospace and Defense
Others
By Geography
North America
United States
Canada
Mexico
South America
Brazil
Argentina
Others
Europe
United Kingdom
Germany
France
Spain
Others
Middle East and Africa
Saudi Arabia
United Arab Emirates
Others
Asia Pacific
China
Japan
India
South Korea
Taiwan
Others
Table of Contents
1. EXECUTIVE SUMMARY
1.1. Key Findings
1.2. Strategic Outlook
2. MARKET SNAPSHOT
2.1. Market Overview
2.2. Market Definition
2.3. Scope of the Study
2.4. Market Segmentation
3. BUSINESS LANDSCAPE
3.1. Market Drivers
3.1.1. Hyperscale Deployment of Generative and Agentic AI
3.1.2. Demand for Higher Token Throughput per Watt
3.1.3. Growth of Locally Executed AI in Devices and Machines
3.1.4. Commercialization of Proprietary Cloud Silicon
3.1.5. AI Computing Capacity Outside Established Technology Centers
3.2. Market Restraints
3.2.1. Constraints in HBM, Packaging and Leading-Edge Capacity
3.2.2. Software Portability and Framework Dependence
3.2.3. Electricity, Rack Density and Site Commissioning
3.2.4. Export Controls and Fragmented Regional Product Requirements
3.2.5. Economic Risk in Concentrated Customer Programs
3.3. Market Opportunities
3.4. Porter’s Five Forces Analysis
3.5. Industry Value Chain Analysis
3.6. Policies and Regulations
3.7. Strategic Recommendations
4. TECHNOLOGICAL OUTLOOK
4.1. GPU and ASIC Architecture
4.2. Advanced Packaging and Chiplet Design
4.3. HBM and Memory Movement
4.4. Edge AI Processing
4.5. Semiconductor Process Nodes and Yield
5. AI ACCELERATOR CHIPS MARKET BY CHIP TYPE
5.1. Introduction
5.2. GPU
5.3. ASIC
5.4. FPGA
5.5. CPU
5.6. TPU
5.7. NPU
5.8. Others
6. AI ACCELERATOR CHIPS MARKET BY PROCESSING TYPE
6.1. Introduction
6.2. Edge
6.3. Cloud
7. AI ACCELERATOR CHIPS MARKET BY APPLICATION
7.1. Introduction
7.2. Natural Language Processing
7.3. Computer Vision
7.4. Robotics
7.5. Autonomous Driving
7.6. Generative AI
7.7. High-Performance Computing
7.8. Others
8. AI ACCELERATOR CHIPS MARKET BY INDUSTRY
8.1. Introduction
8.2. Automotive
8.3. Consumer Electronics
8.4. Healthcare
8.5. Manufacturing
8.6. BFSI
8.7. IT and Telecommunications
8.8. Retail and E-commerce
8.9. Aerospace and Defense
8.10. Others
9. AI ACCELERATOR CHIPS MARKET BY GEOGRAPHY
9.1. Global Overview
9.2. North America
9.2.1. By Country
9.2.1.1. United States
9.2.1.2. Canada
9.2.1.3. Mexico
9.3. South America
9.3.1. By Country
9.3.1.1. Brazil
9.3.1.2. Argentina
9.3.1.3. Others
9.4. Europe
9.4.1. By Country
9.4.1.1. United Kingdom
9.4.1.2. Germany
9.4.1.3. France
9.4.1.4. Spain
9.4.1.5. Others
9.5. Middle East and Africa
9.5.1. By Country
9.5.1.1. Saudi Arabia
9.5.1.2. United Arab Emirates
9.5.1.3. Others
9.6. Asia Pacific
9.6.1. By Country
9.6.1.1. China
9.6.1.2. Japan
9.6.1.3. India
9.6.1.4. South Korea
9.6.1.5. Taiwan
9.6.1.6. Others
10. COMPETITIVE ENVIRONMENT AND ANALYSIS
10.1. Major Players and Strategy Analysis
10.2. Market Share Analysis
10.3. Mergers, Acquisitions, Agreements and Collaborations
10.4. Competitive Dashboard
11. COMPANY PROFILES
11.1. NVIDIA Corporation
11.2. Advanced Micro Devices, Inc.
11.3. Broadcom Inc.
11.4. Marvell Technology, Inc.
11.5. Intel Corporation
11.6. Qualcomm Incorporated
11.7. MediaTek Inc.
11.8. Alphabet Inc. (Google)
11.9. Amazon.com, Inc. (AWS)
11.10. Microsoft Corporation
11.11. Meta Platforms, Inc.
11.12. Huawei Technologies Co., Ltd.
11.13. Cerebras Systems Inc.
12. APPENDIX
12.1. Currency
12.2. Assumptions
12.3. Base and Forecast Years Timeline
12.4. Key Benefits for Stakeholders
12.5. Research Methodology
12.6. Abbreviations





Frequently asked questions
What is the projected market size and growth rate for AI accelerator chips?
The AI Accelerator Chips Market will reach $780 billion by 2031, growing at a 21.1% CAGR.
Which chip design accounts for the largest market share in 2026?
GPU designs comprise an estimated 78% of accelerator-chip value in 2026.
What is the principal purchasing channel for AI accelerator chips?
Cloud-based deployment remains the primary purchasing channel.
Which types of chips are gaining ground in repeatable AI workloads?
Dedicated inference ASICs and hyperscaler silicon are gaining ground.
Which region leads in AI accelerator chip procurement and future demand?
North America leads procurement; Asia Pacific gains deployed demand through 2031.
What factors increasingly influence access to leading AI processors?
HBM delivery, wafer capacity, and advanced packaging reservations are key.
Cite this report
Knowledge Sourcing Intelligence. (Oct 2026). AI Accelerator Chips Market - Strategic Insights and Forecasts (2026-2031). https://www.knowledge-sourcing.com/report/ai-accelerator-chips-market