
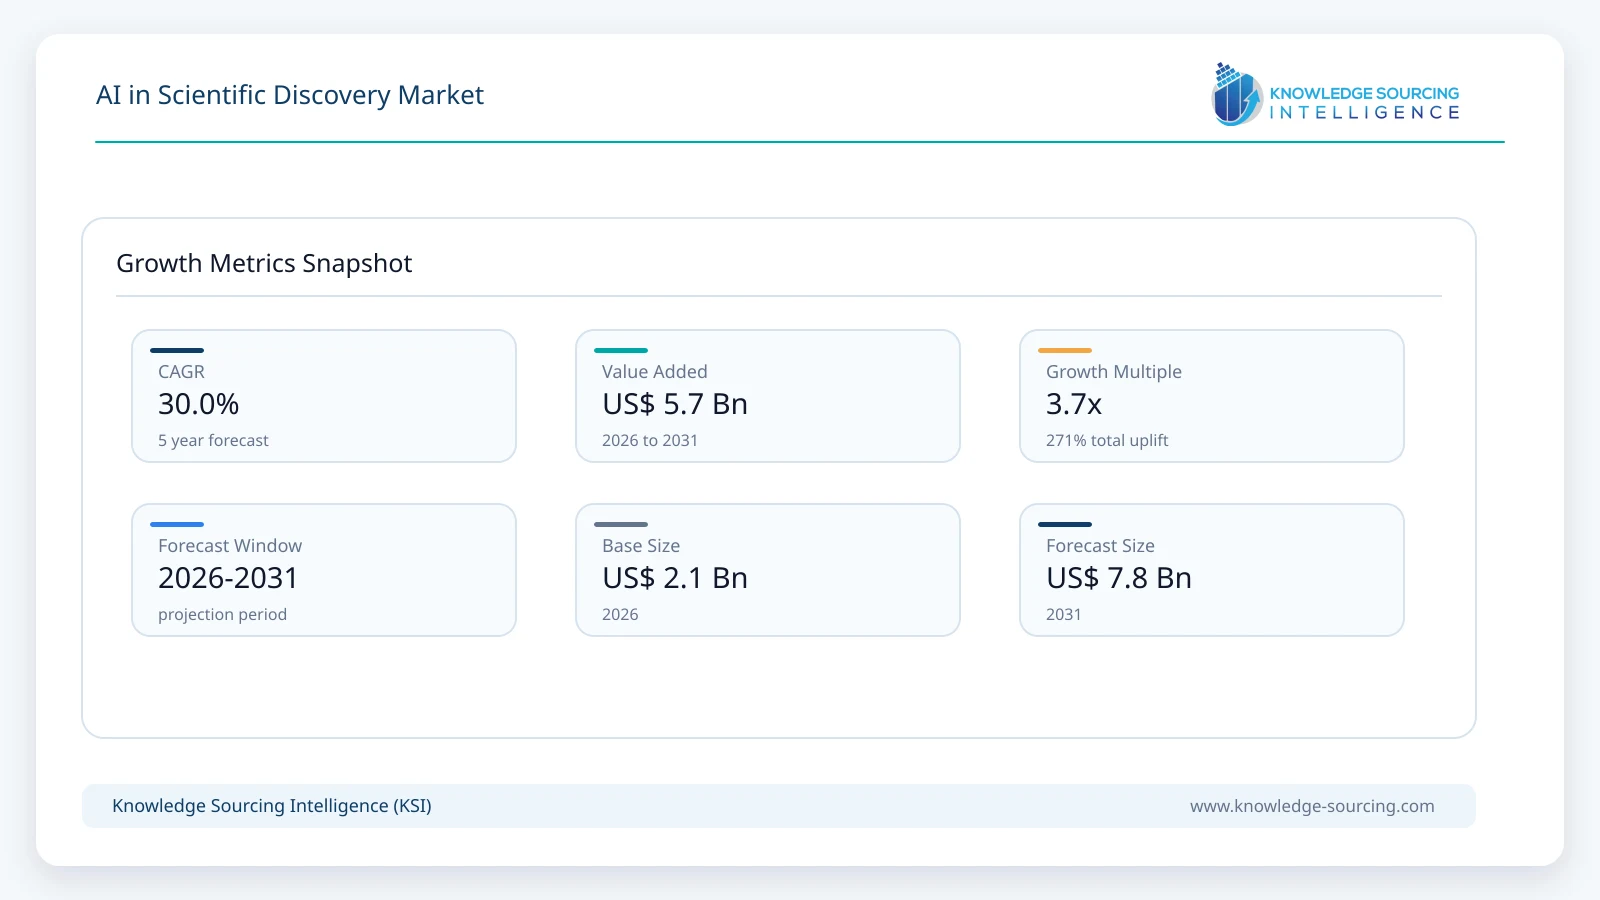
The AI in Scientific Discovery Market is estimated at USD 2.10 billion in 2026 and USD 7.80 billion in 2031, representing 30.0% CAGR over the forecast period.
Highlights:
- 1Drug discovery and pharmaceuticals lead the commercial application landscape, supported by mature research budgets and defined experimental pathways.
- 2Cloud-based deployment supports large model runs and collaborative research, although proprietary data and national laboratory rules sustain hybrid and on-premise configurations.
- 3Pharmaceutical and biotechnology companies are the most commercially developed end-user group; research institutes influence methods and open-model adoption.
- 4Independent experimental confirmation remains the central barrier between attractive computational predictions and defensible scientific outcomes.
- 5North America has the deepest established supplier and funding ecosystem, while Asia Pacific has expanding demand from biotechnology, chemistry and national computing initiatives.
- 6Competition depends on proprietary scientific context, integration into instruments and research records, and the ability to reproduce results, not merely model parameter counts.
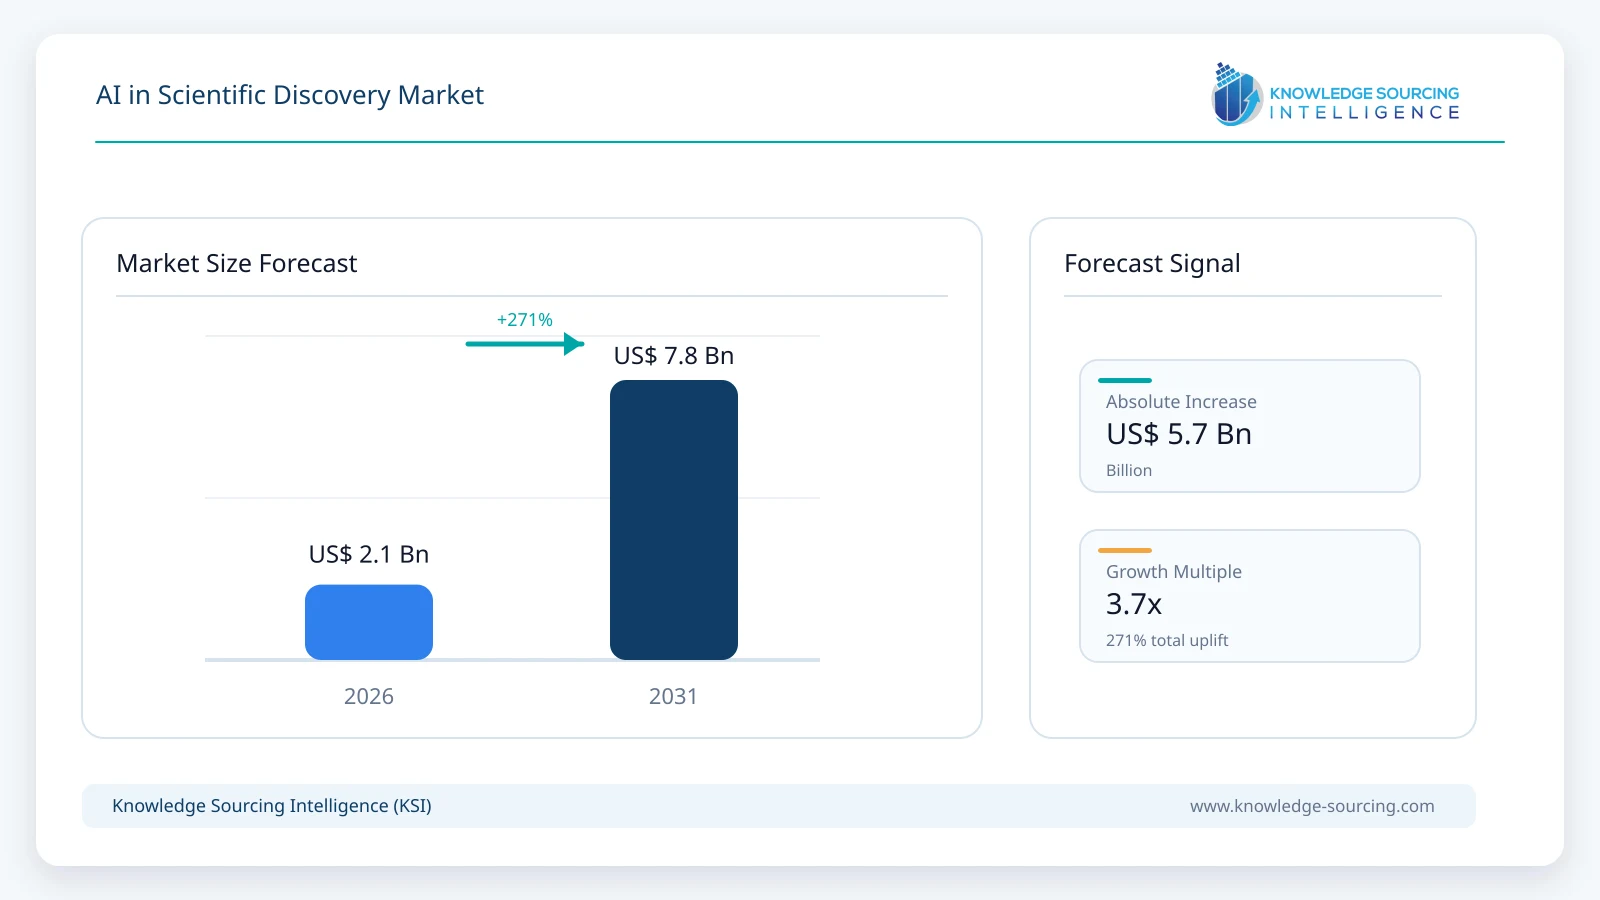
Scientific-discovery AI covers purpose-built software, foundation models, simulation and analytical platforms used to generate, test or prioritize research hypotheses. In practical workflows, it may interpret genomic measurements, rank candidate molecules, recommend compositions for a polymer or schedule a series of experiments. The commercial activity sits in domain software, specialist platform services, research collaborations and identifiable AI-enabled analytical work. Experimental equipment and underlying cloud capacity form part of the delivery environment but should not be mistaken for scientific-software revenue in their entirety.
A biologist screening new targets has different evidence requirements from an industrial chemist optimizing a formulation. The former may demand independent assays, disease relevance and a convincing mechanism; the latter must reproduce specified properties across process settings, batches and raw-material variability. Such distinctions affect data contracts, model design and support intensity. Buyers typically involve domain scientists, research informatics teams and procurement managers, which makes scientific validation and implementation fit just as important as model benchmarks.
The market brings together specialist discovery companies, research-informatics suppliers, cloud and accelerated-computing providers, and organizations operating proprietary research platforms. They do not sell interchangeable products. Some earn subscription fees, others receive collaborative research payments or milestones, while certain research models are openly released. Customer spending should therefore be assessed at the level of identifiable products and services rather than inferred from total research grants, laboratory capital expenditure or the headline value of pharmaceutical partnerships.
On 7 July 2026, Citrine Informatics introduced Catalyst and Apex to simplify the creation of materials AI workflows and strengthen prediction quality. That release is relevant because experimental design, not the theoretical accuracy of a stand-alone model, is frequently where a materials manufacturer sees cost savings. A useful system connects composition and processing records with the next laboratory run, documents the reasoning behind the recommendation and retains the eventual measurement. The performance of that feedback loop can shape how extensively a platform is deployed across formulation, product engineering and production-support teams.
Life-science procurement is developing along a separate route. Insilico Medicine's July 2026 Takeda agreement includes roughly USD 60 million in initiation, near-term and milestone payments, with a larger contingent value subject to later achievements. A contractual ceiling is not earned sales, but the structure demonstrates how model-driven candidate generation can be embedded in an established pharmaceutical development program. Recursion's August 2026 advancement of a neuroscience target with Genentech provides another early scientific milestone. Neither event establishes that a drug will reach approval; both show the commercial premium placed on targets that can survive experimental review.
Public research infrastructure can expand the user base without creating equivalent private revenue. The US Department of Energy launched its Genesis Open Models initiative in August 2026 with the aim of producing adaptable scientific foundation models. Such releases can lower the entry cost for laboratories and attract developers of supplementary tools, but open weights also constrain the price that commercial vendors can charge for undifferentiated model access. Suppliers with reliable proprietary experimental data, specialized support and validated applications are better insulated from this pressure.
Market Trends
Experimental design is moving closer to routine materials R&D
Materials informatics is progressing from retrospective correlation to the selection of experiments under measurable property constraints. Citrine's Catalyst and Apex launches illustrate a practical change: chemists can specify performance goals and examine recommendations within research records that already contain composition, processing and test results. Adoption is likely to be strongest where each new experiment is costly or capacity-constrained, including specialty chemicals, coatings and battery materials. Industrial validation remains necessary when a prediction is sensitive to manufacturing scale or lot variation.
Production scale remains the decisive test. A coating or electrode formulation may satisfy a bench-scale prediction and still prove unstable when raw-material lots change, a mixing sequence is altered or an instrument is recalibrated. For the purchaser, experiment recommendation software becomes more valuable when it tracks these operating conditions and learns from rejected batches. This creates a defensible opportunity for materials-platform suppliers with strong customer-specific data models, but it also requires longer onboarding than a standalone prediction service.
Life-science platforms are closing the loop between models and assays
Recursion and Genentech advanced their first neuroscience target into a joint early discovery program in August 2026 after target identification and validation work. The significance lies in coupling data-rich phenotypic systems with biological review before proceeding to molecule generation. Vendors able to link model outputs to measured activity, assay provenance and updated hypotheses can deepen relationships with discovery teams. The evidence threshold grows higher as a program approaches animal studies and regulated development, limiting the usefulness of stand-alone demonstration models.
The economics of a closed-loop program depend on throughput as much as model sophistication. Automated assays are expensive when plate formats, robotics and sample preparation cannot be reused, while unstructured laboratory records limit retraining. Discovery partners that capture failed assays alongside successful hits improve their chance of reducing repeat work. Scientific teams nevertheless retain responsibility for deciding whether a target can advance; an early candidate progressing into joint research is not evidence of regulatory approval or eventual drug revenue.
Scientific agents are acquiring specialized computational tools
NVIDIA's BioNeMo Agent Toolkit, announced in June 2026, makes molecular modeling, sequence analysis and related computational functions callable within agent-led workflows. This architecture can remove repetitive handoffs between software packages, yet an agent's completed workflow must be judged against the scientific validity of its inputs and outputs. Research organizations are likely to demand logged model calls, reproducible environments and human sign-off before permitting systems to initiate costly or safety-sensitive experiments.
Laboratory agents are increasingly assessed by their ability to execute a bounded calculation and show the exact inputs used. Benchling's October 2026 Science Foundries announcement, still in customer preview, illustrates a shift toward controlled chains of agent actions with scientist approval at key steps. A platform that calls a docking tool, records the scoring settings and routes a result for confirmation has a more useful compliance story than an assistant that returns an unsourced conclusion. Agent pricing will also need to account for repeated calls, retries and computationally intensive models.
Shared foundation models are widening research access
The Department of Energy's Genesis Open Models program proposes adaptable open-weight scientific models for laboratories and research institutions. A shared starting point may help smaller teams work on domain questions without financing every stage of pretraining. It may also redirect vendor opportunities toward deployment engineering, domain fine-tuning, validated datasets and specialist interfaces. Restrictive data licenses and export rules could still prevent common models from being used uniformly across international collaborations.
A publicly funded foundation model can reduce the cost of entering a technical field while leaving the last mile of validation expensive. Data preparation, domain adaptation, instrument integration and controlled access to protected datasets remain paid work. Commercial suppliers must therefore establish an advantage in reliability and implementation, not merely distribute weights developed elsewhere. The benefit to universities may be considerable even when it yields no directly comparable vendor subscription revenue.
Genomics systems are becoming reference resources
Google DeepMind introduced AlphaGenome Atlas in September 2026 with predictions covering roughly nine billion possible single-letter DNA changes. Academic availability of a large predictive reference set can support variant prioritization and experimental planning, particularly where researchers cannot test every possibility. It does not settle whether an individual change causes disease. Commercial tools that place such predictions alongside sequencing quality, population evidence and functional assays will be evaluated more favorably than systems presenting computational scores as final biological conclusions.
Variant prediction has immediate research utility when it helps prioritize which candidate changes deserve functional testing. Clinical relevance remains a separate question: population frequency, assay quality, tissue context and phenotype must be considered before making a disease claim. Suppliers integrating genomic models with laboratory information systems can charge for workflow fit and traceable evidence, but blanket claims that computational predictions replace validated biological testing would misstate the product. Open genomic resources also create price pressure for undifferentiated scoring tools.
AI in Scientific Discovery Market Segment Analysis
By Application
Drug Discovery & Pharmaceuticals
Drug Discovery & Pharmaceuticals is the largest commercial application in the KSI classification. Under the independent allocation, its attributable value rises from approximately USD 1.03 billion in 2026 to USD 3.59 billion in 2031, as buyers expand from target discovery into candidate ranking, structure-informed design and repeated experimental cycles. Insilico Medicine and Recursion operate through different models: contracted molecule design and data-led target validation. Scientific confidence, not the volume of generated structures, determines whether a recommendation survives the laboratory. Milestone-rich agreements can be valuable to suppliers, but contingent payments must not be booked as current scientific-software revenue.
The commercial question for a drug developer is whether a discovery platform selects better experiments under its own constraints. A proposed binding interaction must withstand biochemical assays, while a nominated disease target must establish functional relevance in a credible model. Materials science is a sizeable adjoining application, particularly when a manufacturer can measure reductions in unsuccessful synthesis or formulation work. Purchases in either industry are more likely to recur when the platform retains experimental provenance and learns from negative results.
By Deployment Mode
Cloud-Based
Cloud-Based deployment represents about USD 1.28 billion of the independent 2026 estimate, reflecting demand for elastic compute, hosted scientific models and collaboration between geographically separated research teams. It offers drug designers and materials scientists periodic access to high-throughput inference without financing a dedicated GPU cluster. Cloud contracts are not interchangeable with scientific AI revenue: only the identifiable application and discovery-attributable services enter this market, not a customer’s total cloud infrastructure bill.
The cloud segment could reach approximately USD 5.07 billion by 2031, equivalent to a modeled CAGR of 31.7%. This growth depends on domain software becoming an ordinary laboratory tool rather than a trial purchased against short-lived project funds. Highly sensitive structures, proprietary assay records and restricted national-laboratory data continue to sustain hybrid and on-premise deployments. Purchasers increasingly want isolation of customer data, reproducible runtime environments and control over whether records can be used in model training.
By End-User
Pharmaceutical & Biotechnology Companies
Pharmaceutical & Biotechnology Companies are the leading end-user group, with modeled attributable spending of about USD 0.95 billion in 2026. Large drug developers purchase specialist target discovery, protein design and computational chemistry through multi-year programs; smaller biotechnology firms more often pay for a narrower set of models and validation work. The contractual distinction matters: a discovery-services fee, a subscription and the prospective value of downstream intellectual property are separate commercial items, even when one partnership includes all three.
For 2031, the corresponding end-user allocation is approximately USD 3.35 billion, reflecting the move from individual research teams to platform-wide procurement. The approval process is seldom limited to informatics staff. Discovery scientists, legal teams and data-governance officers must agree on experimental criteria, model update rules and ownership of generated molecular or materials designs. Universities and government laboratories develop important methods and provide access to shared infrastructure, but their research awards cannot automatically be converted into software-sales estimates.
Market Drivers
Pharmaceutical R&D rewards better early-stage selection
Screening resources remain finite even when computational libraries become enormous. Discovery groups gain commercially when models help exclude weak candidates before expensive synthesis, assays or development work. Takeda's July 2026 collaboration with Insilico illustrates the willingness to pay for a defined discovery role, provided candidate quality can be assessed against predetermined criteria. Long-term demand should favor platforms whose ranking or molecular-design results improve the selection of experimental work, rather than those promising unqualified reductions in drug-development timelines.
The buying rationale is clearest where a pharmaceutical organization can compare model-guided choices with its historical assay funnel. Decision-makers want to know how many nominated targets proved reproducible, how much synthesis or biology capacity was avoided and whether success generalizes to a second program. Contracts therefore tend to involve access to proprietary assays and staged deliverables. The vendor that improves the quality of a decision can command a stronger position than one offering inexpensive but poorly calibrated predictions.
Automated laboratories create repeated, usable feedback
High-throughput instruments and automated experiments generate the repeated observations needed to refine scientific models. When assay conditions and unsuccessful experiments are captured with the results, researchers can distinguish reproducible effects from data artifacts. Recursion's tightly coupled computation and experimentation strategy is one example of this approach. Commercial value arises from higher-quality scientific decisions across successive programs; investment requirements include metadata standards, instrument connectivity and ongoing stewardship of experimental histories.
Instruments alone do not create learning. An assay record must preserve the sample identity, the control conditions, instrument settings and a link to the downstream analytical result. Specialist software vendors can capture value by integrating these records, especially when a customer has several laboratories using different laboratory information management systems. Adoption may be slowed by the expense of standardizing the experiments already under way, but a common record reduces the manual work needed to reproduce an apparent improvement.
Specialized computing tools broaden model adoption
Researchers can now access callable structure-prediction and design tools without implementing every underlying algorithm themselves. NVIDIA's June 2026 BioNeMo release demonstrates how a common agent interface can expose scientific computation across multiple laboratories and software environments. This lowers some integration burdens for tool vendors and research groups. It does not remove the need for scientific expertise, infrastructure spending or verification, but it expands the number of workflows in which an organization can trial advanced models.
This accessibility also changes how smaller scientific-software businesses compete. They can build a domain application around a validated open or licensed model rather than develop the entire computational stack. Benchling's Model Hub and NVIDIA's BioNeMo toolkit show contrasting approaches to that opportunity. The commercial moat sits in the quality of data connections, model evaluation and the documented handoff into a scientist's existing workflow, where inconsistent units or missing metadata can invalidate an otherwise sound algorithm.
National programs support shared scientific infrastructure
Government agencies are funding computing capabilities that individual research laboratories would struggle to maintain. The US Department of Energy's Genesis initiative and open-model program indicate support for AI-enabled research across energy, materials and other physical sciences. Shared infrastructure can build institutional familiarity with scientific models and help commercial providers reach new users through integrations and specialized services. Public funding should be interpreted as an enabling input rather than as direct evidence of private market sales.
The spending effect is indirect. Open-model programs and shared GPU capacity create demand for training, deployment and interoperable research tools, but a public model release is not itself a software sale. Procurement follows the grant cycle, institution-specific cybersecurity reviews and the technical maturity of the laboratory. Commercial partners with existing research-informatics installations may convert this access into paid services more easily than providers that require complete migration to a new research environment.
Industrial R&D seeks to reduce costly experimental iteration
The cost of synthesizing, characterizing and scaling a new material often exceeds the cost of computing a prediction. Manufacturers can therefore justify scientific AI when it reduces unnecessary trials or identifies promising combinations under multiple performance constraints. Citrine's 2026 product work emphasizes recommended experiments and traceable modeling, which are relevant to this purchasing logic. Customers still need to establish that laboratory optimization transfers to plant conditions; the strongest initial use cases tend to have stable, structured process data and clear test metrics.
Process chemists also need models capable of explaining when a recommendation is outside the range of reliable observations. A formulation optimizer trained on a narrow set of inputs may propose an attractive but physically impractical material. Platforms that expose uncertainty, constrain suggestions to available feedstocks and incorporate manufacturing tolerances can influence procurement beyond the initial data-science group. Economic returns are most credible in repeated development cycles, where fewer wasted tests can be documented against real laboratory budgets.
Market Restraints
Research data are heterogeneous and often incomplete
An experimental dataset may combine measurements generated under different protocols, instruments, sample preparation conditions and reporting conventions. Model performance can deteriorate when these differences are hidden in a consolidated table. In chemistry, negative and failed experiments are especially likely to be missing, distorting the apparent search space. Vendors must invest in cleaning, provenance and uncertainty estimation before broader automation is safe. These costs are often borne by customers before the first measurable productivity benefit emerges.
Data rights complicate the repair. Laboratories sometimes lack permission to pool results across collaborators or even reuse data collected under an earlier commercial agreement. Materials records may also omit temperatures, humidity and operator actions needed to explain an outcome. Before offering a recurring AI contract, suppliers frequently must fund a substantial amount of customer-specific ontology and metadata work. These fixed costs reduce margins on small accounts and can delay conversion from paid pilots into enterprise deployments.
Predictions still require independent scientific validation
A target ranked highly by a model may fail to affect disease biology when tested in relevant systems. Likewise, a candidate material may meet predicted characteristics under simulation yet prove unstable when synthesized. Scientific buyers require blinded testing, out-of-sample evaluation and replication before they rely on AI-supported results for expensive decisions. These checks lengthen sales cycles and make flashy public demonstrations poor proxies for sustained commercial deployment. The same concern limits the scope for unattended laboratory agents.
The evidence requirement is strongly application-specific. A generated protein structure may be useful for selecting a binding assay but not prove stability in a living system; an optimized catalyst may behave differently after scale-up. Scientists need uncertainty estimates and predefined success criteria rather than a single impressive benchmark. Contracts can be restructured around staged technical acceptance, slowing recognized service revenue but giving customers clearer reasons to expand access if experiments reproduce the promised benefit.
Compute intensity can offset early productivity gains
Training and repeatedly running large biological or physical models can involve substantial GPU capacity, data movement and specialist engineering. Cloud access reduces upfront equipment commitments but exposes laboratories to variable consumption bills. Internal research groups may respond by shrinking models, scheduling jobs, using shared university infrastructure or retaining smaller local systems. Suppliers with efficient algorithms and transparent consumption controls are better positioned than those dependent on high-cost experiments without a defensible financial return.
Consumption pricing is particularly difficult when an autonomous agent can repeat a failed analysis without a scientist explicitly requesting each run. Model vendors are under pressure to log computational spend by research program, limit expensive retries and provide less costly inference alternatives for routine work. Universities and smaller research organizations have additional constraints because shared clusters are allocated competitively. Efficiency gains must therefore be demonstrated at the level of cost per useful experiment, not model speed in isolation.
Intellectual-property controls complicate collaboration
Drug structures, unpublished assay results and advanced-material formulations are strategically sensitive assets. Pharmaceutical partners may allow a model provider to process data while prohibiting reuse for training or work with another customer. Government laboratories can face additional export, cybersecurity and access restrictions. These contractual boundaries can prevent the pooling of data that would otherwise improve model performance. Deployments consequently require clear rights over datasets, derived features, generated outputs and model improvements.
The concern extends to the model itself. A platform fine-tuned using proprietary molecule libraries may encode valuable insights that a customer does not want reused in future work for another company. Buyers increasingly distinguish access to third-party foundation models, private weights and contractually isolated hosted environments. Service providers that can prove data segregation and clear rights to generated compounds or candidate materials may win business despite higher prices, especially in regulated and strategically sensitive research.
Attribution of economic results remains difficult
Research output is influenced by scientists, instrumentation, existing literature, validation design and AI tools used together. A faster molecular screen does not prove that the resulting therapeutic will clear later development. Similarly, a materials model may only address one of several production bottlenecks. When suppliers charge fees, milestone payments and compute costs across a single research program, buyers struggle to isolate the value provided by each element. That uncertainty can slow renewal decisions and discourage procurement beyond pilot deployments.
Published collaboration announcements often combine upfront cash, scientific services, future milestones and eventual royalties. These are not additive measures of a platform's annual market revenue. Even within a research group, scientists may use several models in one successful project, making direct return-on-investment calculations uncertain. Procurement teams tend to respond with shorter evaluations and narrowly defined experiments before granting portfolio-wide access. Suppliers lacking auditable performance and billing records face a longer path to recurring contracts.
Regional Outlook
North America
Established commercial and research ecosystem
North America is the leading regional commercial base in the modeled allocation, at approximately USD 0.88 billion in 2026, equivalent to 42% of the indicative global market. The United States combines pharmaceutical research groups, specialized scientific-software suppliers and well-funded national laboratories; Canada adds university and biotechnology demand. NVIDIA, Recursion and Citrine reach different parts of this ecosystem through research-tool infrastructure, discovery partnerships and materials software. Government research spending supports technical adoption, but a public computing grant should not be counted again as a commercial platform sale.

The region is projected to reach approximately USD 2.81 billion in 2031, implying about 26.1% annual growth under the independent scenario. Its global share moderates to 36% as other regions broaden their commercial research base. Continued purchasing depends on reproducible model performance, secure access to proprietary laboratory data and the ability to integrate proposed experiments with actual instruments. Large customers may consolidate suppliers to simplify validation and governance, creating a competitive advantage for platforms embedded in the scientific record.
Asia Pacific
Rapid expansion in specialized research capacity
Asia Pacific represents approximately USD 0.48 billion of the independent 2026 global allocation, or 23%, and is modeled as the fastest-growing regional market. China, Japan, South Korea, Taiwan and India participate through different combinations of pharmaceutical research, advanced materials, semiconductor science and publicly supported computing. The region also includes companies building their own discovery platforms rather than simply purchasing software developed overseas. Intellectual-property protections, national research priorities and access to computing infrastructure shape local adoption.
On the same basis, Asia Pacific could approach USD 2.42 billion in 2031, equivalent to approximately 38.0% CAGR and a 31% global share. This is a modeled scenario rather than a KSI-published regional forecast. Growth will be uneven: established laboratories may buy cloud model access or licensed scientific applications, whereas organizations with tighter cross-border data rules may procure private deployments. Vendors with local validation partners and the ability to demonstrate experimental improvement across language and process differences are more likely to convert scientific interest into recurring revenue.
Competitive Landscape
The competitive landscape divides between drug-discovery specialists, domain research-software companies and providers of scientific computing tools. Insilico Medicine and Recursion combine proprietary experimental or biological platforms with paid discovery collaborations. Citrine supplies industrial materials prediction and experiment-selection software, while Schrödinger sells physics-based molecular simulation and AI-enabled drug-design tools. Revvity Signals and Benchling provide research workflow infrastructure with embedded analytical and AI features. These are materially different business models; ranking them by consolidated company revenue would distort their share of the defined market.
BenevolentAI retained its scientific-discovery brand after its 2025 restructuring and delisting, but should not be presented as a separately listed company. Atomwise participates through AI-supported molecular discovery partnerships. Google DeepMind contributes scientific models, while NVIDIA offers BioNeMo applications and agent toolkits; open scientific releases are not evidence of equivalent software licensing revenue. The practical basis for competition is access to validated domain data, integration with scientific instruments, computational efficiency and ownership terms for new intellectual property. Buyers have little reason to pay a premium for a model output that cannot be reproduced.
Recent Developments
21 October 2026: NVIDIA and UW Medicine Institute for Protein Design
NVIDIA introduced the RFD4-Proteina open model for programmable protein design, with reported computational design benchmarks. Its research value will depend on laboratory confirmation of proposed proteins; the announcement does not establish a finished therapeutic product.
15 October 2026: Benchling
Benchling introduced Science Foundries for coordinating scientific agents, models and research workflows, with the offering described as being in customer preview. Human approval remains part of key experimental decisions, distinguishing an announced architecture from a fully autonomous laboratory deployment.
7 August 2026: US Department of Energy
The Department of Energy launched its Genesis Open Models initiative, requesting partners to contribute open-weight models, scientific datasets and evaluation work. Genesis-Science-1 was identified as a planned foundation model, not a deployed commercial product.
5 August 2026: Recursion and Genentech
Genentech advanced the collaboration's first experimentally validated neuroscience target into a joint early drug-discovery program. It represents an early research milestone rather than clinical evidence or pharmaceutical approval.
7 July 2026: Citrine Informatics
Citrine released Catalyst and Apex, adding conversational workflow creation and improved predictive modeling to its materials and chemicals AI platform. The tools target the selection of experiments around defined product-development goals.
2 July 2026: Insilico Medicine and Takeda
Insilico disclosed an AI-powered drug-discovery collaboration using Pharma.AI. Potential milestone and future development value should be distinguished from recognized research fees and from payments contingent on later progress.
Market Outlook
Commercial momentum will depend on moving scientific AI from occasional pilots into measured laboratory programs. Molecular discovery already has established partnership mechanisms, but sustained revenue will require better selection of targets and compounds across repeated projects. In materials R&D, the near-term opportunity lies in reducing trial cycles where formulation histories are available and test outcomes can be collected promptly. Government models and academic tools will expand access while forcing commercial suppliers to offer deeper scientific integration.
Over the forecast period, laboratories are likely to demand model documentation, usable uncertainty estimates, interoperable research records and clear control of proprietary information. Vendors with strong links between computation and physical experiments should be better placed to retain contracts, especially in highly regulated or capital-intensive settings. Predictions about revenue growth remain less reliable than evidence of funded deployments, renewal activity and independently reproduced research outcomes; those measures will offer a clearer picture of market maturity.
AI in Scientific Discovery Market Scope
| Report Metric | Details |
|---|---|
| Total Market Size in 2026 | USD 2.10 billion |
| Total Market Size in 2031 | USD 7.80 billion |
| Forecast Unit | Billion |
| Growth Rate | 30.0% |
| Study Period | 2021 to 2031 |
| Historical Data | 2021 to 2024 |
| Base Year | 2025 |
| Forecast Period | 2026 – 2031 |
| Segmentation | Application, Deployment Mode, End User, Geography |
| Companies |
|
| Customization Scope | 15% Free Customization included with purchase — Request Custom Breakdown → |
| Sample & Data Access | PDF Sample, Excel Databook & Analyst Briefing — Download Free Sample → |
Market Segmentation
By Application
Drug Discovery & Pharmaceuticals
Materials Science & Engineering
Genomics & Molecular Biology
Climate & Environmental Science
Physics, Quantum & Chemistry Research
Astronomy & Space Science
Agricultural & Food Science
By Deployment Mode
Cloud-Based
On-Premise
Hybrid Deployment
By End User
Pharmaceutical & Biotechnology Companies
Chemical & Materials Manufacturers
Academic & Research Institutions
Government Research Agencies & Laboratories
Space & Defense Organizations
Technology & AI Solution Providers
By Geography
North America
USA
Canada
Mexico
South America
Brazil
Argentina
Others
Europe
United Kingdom
Germany
France
Spain
Others
Middle East and Africa
Saudi Arabia
UAE
Others
Asia Pacific
China
Japan
India
South Korea
Taiwan
Others
Table of Contents
1. EXECUTIVE SUMMARY
2. MARKET SNAPSHOT
2.1. Market Overview
2.2. Market Definition
2.3. Scope of the Study
2.4. Market Segmentation
3. BUSINESS LANDSCAPE
3.1. Market Drivers
3.2. Market Restraints
3.3. Market Opportunities
3.4. Porter’s Five Forces Analysis
3.5. Industry Value Chain Analysis
3.6. Policies and Regulations
3.7. Strategic Recommendations
4. TECHNOLOGICAL OUTLOOK
5. AI IN SCIENTIFIC DISCOVERY MARKET BY APPLICATION
5.1. Introduction
5.2. Drug Discovery & Pharmaceuticals
5.3. Materials Science & Engineering
5.4. Genomics & Molecular Biology
5.5. Climate & Environmental Science
5.6. Physics, Quantum & Chemistry Research
5.7. Astronomy & Space Science
5.8. Agricultural & Food Science
6. AI IN SCIENTIFIC DISCOVERY MARKET BY DEPLOYMENT MODE
6.1. Introduction
6.2. Cloud-Based
6.3. On-Premise
6.4. Hybrid Deployment
7. AI IN SCIENTIFIC DISCOVERY MARKET BY END USER
7.1. Introduction
7.2. Pharmaceutical & Biotechnology Companies
7.3. Chemical & Materials Manufacturers
7.4. Academic & Research Institutions
7.5. Government Research Agencies & Laboratories
7.6. Space & Defense Organizations
7.7. Technology & AI Solution Providers
8. AI IN SCIENTIFIC DISCOVERY MARKET BY GEOGRAPHY
8.1. Introduction
8.2. North America
8.2.1. USA
8.2.2. Canada
8.2.3. Mexico
8.3. South America
8.3.1. Brazil
8.3.2. Argentina
8.3.3. Others
8.4. Europe
8.4.1. United Kingdom
8.4.2. Germany
8.4.3. France
8.4.4. Spain
8.4.5. Others
8.5. Middle East and Africa
8.5.1. Saudi Arabia
8.5.2. UAE
8.5.3. Others
8.6. Asia Pacific
8.6.1. China
8.6.2. Japan
8.6.3. India
8.6.4. South Korea
8.6.5. Taiwan
8.6.6. Others
9. COMPETITIVE ENVIRONMENT AND ANALYSIS
9.1. Major Players and Strategy Analysis
9.2. Market Share Analysis
9.3. Mergers, Acquisitions, and Agreements
9.4. Competitive Dashboard
10. COMPANY PROFILES
10.1. Insilico Medicine, Inc.
10.2. Recursion Pharmaceuticals, Inc. (including Exscientia capabilities)
10.3. BenevolentAI (current post-merger entity)
10.4. Citrine Informatics, Inc.
10.5. Google DeepMind (Alphabet Inc.)
10.6. NVIDIA Corporation
10.7. Schrödinger, Inc.
10.8. Revvity Signals
10.9. Atomwise, Inc.
10.10. Benchling, Inc.
11. APPENDIX
11.1. Currency
11.2. Assumptions
11.3. Base Year and Forecast Period Timeline
11.4. Key Benefits for Stakeholders
11.5. Research Methodology
11.6. Abbreviations





Frequently asked questions
What is the projected market size and CAGR for AI in Scientific Discovery?
Market reaches USD 7.80 billion by 2031, with 30.0% CAGR.
Which application area leads the AI in Scientific Discovery market?
Drug discovery and pharmaceuticals lead the commercial application landscape.
What is the central barrier for scientific discovery AI adoption?
Independent experimental confirmation remains the central barrier.
Which region holds the deepest ecosystem for AI in Scientific Discovery?
North America has the deepest established supplier and funding ecosystem.
Which end-user group is most commercially developed?
Pharmaceutical and biotechnology companies are the most commercially developed.
What does Scientific-discovery AI primarily cover?
The AI in Scientific Discovery Market covers purpose-built software, foundation models, simulation, and analytical platforms.
Cite this report
Knowledge Sourcing Intelligence. (Nov 2026). AI in Scientific Discovery Market - Strategic Insights and Forecasts (2026-2031). https://www.knowledge-sourcing.com/report/ai-in-scientific-discovery-market